Adversarial
Verification
Delivering one workflow for convergence and scale at:

%20--%3e%3csvg%20version='1.0'%20id='Layer_1'%20xmlns='http://www.w3.org/2000/svg'%20xmlns:xlink='http://www.w3.org/1999/xlink'%20x='0px'%20y='0px'%20viewBox='0%200%20105%2045.5'%20enable-background='new%200%200%20105%2045.5'%20xml:space='preserve'%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M64.1,25.3c0.5,0.7,0.8,1.5,0.8,2.5c0,1.7-0.6,3-1.7,3.9c-1.1,0.9-2.6,1.3-4.4,1.3%20H51V15.8h7c1.9,0,3.3,0.4,4.4,1.2c1,0.8,1.6,2,1.6,3.6c0,1.3-0.7,2.4-2,3.2C62.9,24.1,63.6,24.6,64.1,25.3z%20M55,22.6h3.2%20c0.4,0,0.8-0.1,1.2-0.4c0.3-0.3,0.5-0.7,0.5-1.2c0-1.2-0.6-1.9-1.9-1.9h-3V22.6z%20M60.1,29.3c0.4-0.3,0.7-0.9,0.7-1.7%20c0-0.7-0.2-1.2-0.7-1.6c-0.4-0.3-1-0.5-1.7-0.5H55v4.2h3.4C59.1,29.8,59.6,29.7,60.1,29.3z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M66.3,18.6h4.2v-3.1h-4.2V18.6z%20M66.4,20.6h4.1l0,13.3h-4.1V20.6z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M83,20.7c1,0.6,1.5,1.5,1.5,2.7v10.4c0,1.9-0.6,3.3-1.7,4.3%20c-1.1,1-2.7,1.5-4.8,1.5c-1.1,0-2-0.1-2.8-0.2c-0.8-0.2-1.4-0.4-1.9-0.6v-3.5c0.5,0.2,1.2,0.5,2.1,0.7c0.9,0.2,1.7,0.3,2.5,0.3%20c1.1,0,1.9-0.2,2.3-0.7c0.4-0.5,0.7-1.1,0.7-1.9v-0.8c-0.9,0.8-1.9,1.2-3.2,1.2c-1.8-0.1-3.2-0.7-4.2-1.8c-1-1.1-1.5-2.7-1.5-4.9%20c0-2.8,0.6-4.8,1.8-5.9c1.2-1.1,3-1.7,5.3-1.7C80.7,19.7,82.1,20,83,20.7z%20M76.4,29.9c0.5,0.7,1.2,1.1,2.1,1.1%20c0.8,0,1.6-0.2,2.3-0.6v-6.2c0-0.9-0.7-1.4-2-1.4c-2.1,0-3.1,1.4-3.1,4.1C75.7,28.2,75.9,29.2,76.4,29.9z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M85.9,33.8h2.8V16.9h-2.8V33.8z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M90.9,15.7h5.8c5.3,0,8,2.9,8,8.6c0,5.8-2.7,8.7-8,8.7h-5.8V15.7z%20M96.4,30.6%20c1.9,0,3.2-0.5,4.1-1.5c0.9-1,1.3-2.6,1.3-4.7c0-2.2-0.4-3.7-1.3-4.7c-0.9-1-2.3-1.5-4.1-1.5h-2.8v12.5H96.4z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M4.5,26.9c0.4,0.9,0.9,1.7,1.4,2.5c3.2-0.6,5.7-2.2,7.6-4.7c1.3-1.7,3.9,0.3,2.6,2%20c-2.2,2.8-5,4.7-8.2,5.6c0.4,0.6,0.9,1.1,1.3,1.7c1.9-0.7,3.3-1.3,4.3-1.8c1.6-0.8,3.7-2.2,5.6-2.2c0.8,0,1.8,0.2,2.7,0.5%20c4.5,1.3,8.3,3.1,12.9,3.9c0.5-0.6,1-1.2,1.5-1.8c-12.8-2.5-21.9-9-21.9-21.2c0-4,1.6-8.7,7.3-8.7c4.6,0,6.1,3,7.3,6.6%20c2.6,7.4,6,9.7,14,9.7c1-3.9,1.5-8.1,1.4-12.4c-1.2-0.9-2.7-1.8-4.4-2.7c0.4,1.3,0.8,2.7,1.2,4.2c0.5,2.1-2.6,2.9-3.2,0.8%20c-0.6-2.4-1.3-4.6-2.1-6.6c-1.2-0.4-2.5-0.8-3.9-1.1c3.7,4.9,2.2,12.3,8.7,11.1c2.2-0.4,2.8,2.8,0.6,3.2C27.5,17.8,35.9,0,21.5,0%20c-7.9,0-9.7,6.3-9.7,12.4c0,1.8,0.3,3.6,0.3,5C12.1,22.2,9.1,25.8,4.5,26.9z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M16.3,40.6c1.8,1.3,3.7,2.5,5.8,3.6c1.5-0.8,4.2-2.4,4.3-2.5%20c-0.5-0.2-0.8-0.3-1-0.4c-1.7-0.7-3.4-1.6-5.3-1.7c-0.5,0-1,0-1.5,0.1c-0.4,0.1-0.9,0.3-1.3,0.5c-0.2,0.1-0.4,0.2-0.6,0.3%20C16.7,40.4,16.4,40.6,16.3,40.6z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M11.5,36.5c0.7,0.7,1.3,1.3,2,1.9l0.4-0.2c1.6-0.8,3.5-2.1,5.3-2.1%20c0.8,0,2.1,0.2,3,0.5c2.7,0.8,5,1.7,7.6,2.5c0.4-0.3,0.7-0.6,1-0.9c0.3-0.3,0.9-0.9,1.1-1c-0.3-0.1-3.1-1.1-3.7-1.3%20c-1.4-0.5-2.8-1-4.2-1.5c-1.4-0.4-3-1-4.4-1c-1.6-0.1-3,0.6-4.4,1.3C14,35.3,12.8,36,11.5,36.5z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M3.5,4.1C2.2,4.8,1,5.6,0,6.3c-0.1,4.4,0.4,8.6,1.4,12.5c1.4-0.7,1.6-2.1,1.5-4.8%20C2.8,10.4,2.7,7.3,3.5,4.1z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M11.8,1.1C10.4,1.5,9,1.9,7.7,2.3C6.8,4.3,6.3,6.1,6.2,8c-0.5,5,1.8,11.7-3.8,14%20c0.2,0.6,0.5,1.3,0.7,1.9C14.1,20.7,4.3,8.5,11.8,1.1z'/%3e%3cpath%20fill-rule='evenodd'%20clip-rule='evenodd'%20d='M42,22.2l0.1-0.2l-0.4,0c-4.1-0.3-7.3-1.3-10-2.9c-2.3-1.5-3.9-3.3-4.7-5.7%20c-0.3-0.8-0.5-1.5-0.7-2.2c-1-3.2-1.7-5.5-4.8-5.5c-3,0-4.5,1.9-4.5,5.8C17.5,21,24.5,27.4,38,30.4l0.1,0l0.1-0.2l0.1-0.1%20c0.1-0.2,0.2-0.4,0.3-0.6c0,0,0,0,0,0c0.1-0.3,0.3-0.5,0.4-0.8c0.1-0.1,0.1-0.2,0.2-0.4c0.1-0.1,0.1-0.3,0.2-0.4l0.1-0.2l0.1-0.2h0%20l0.1-0.2l-0.4-0.1c-5.6-1-10.3-2.9-13.7-5.5c-3.8-3-5.6-7.1-5.1-11.9c0.1-0.9,0.6-1.2,1.1-1.2c0.5,0,1.1,0.4,1.3,1.3%20c1.9,7.8,5.6,13.1,17.9,15l0.1,0l0.1-0.2l0-0.1l0.1-0.3c0.1-0.3,0.2-0.5,0.3-0.8c0.1-0.3,0.3-0.6,0.4-1l0-0.1L42,22.2L42,22.2z'/%3e%3c/svg%3e)



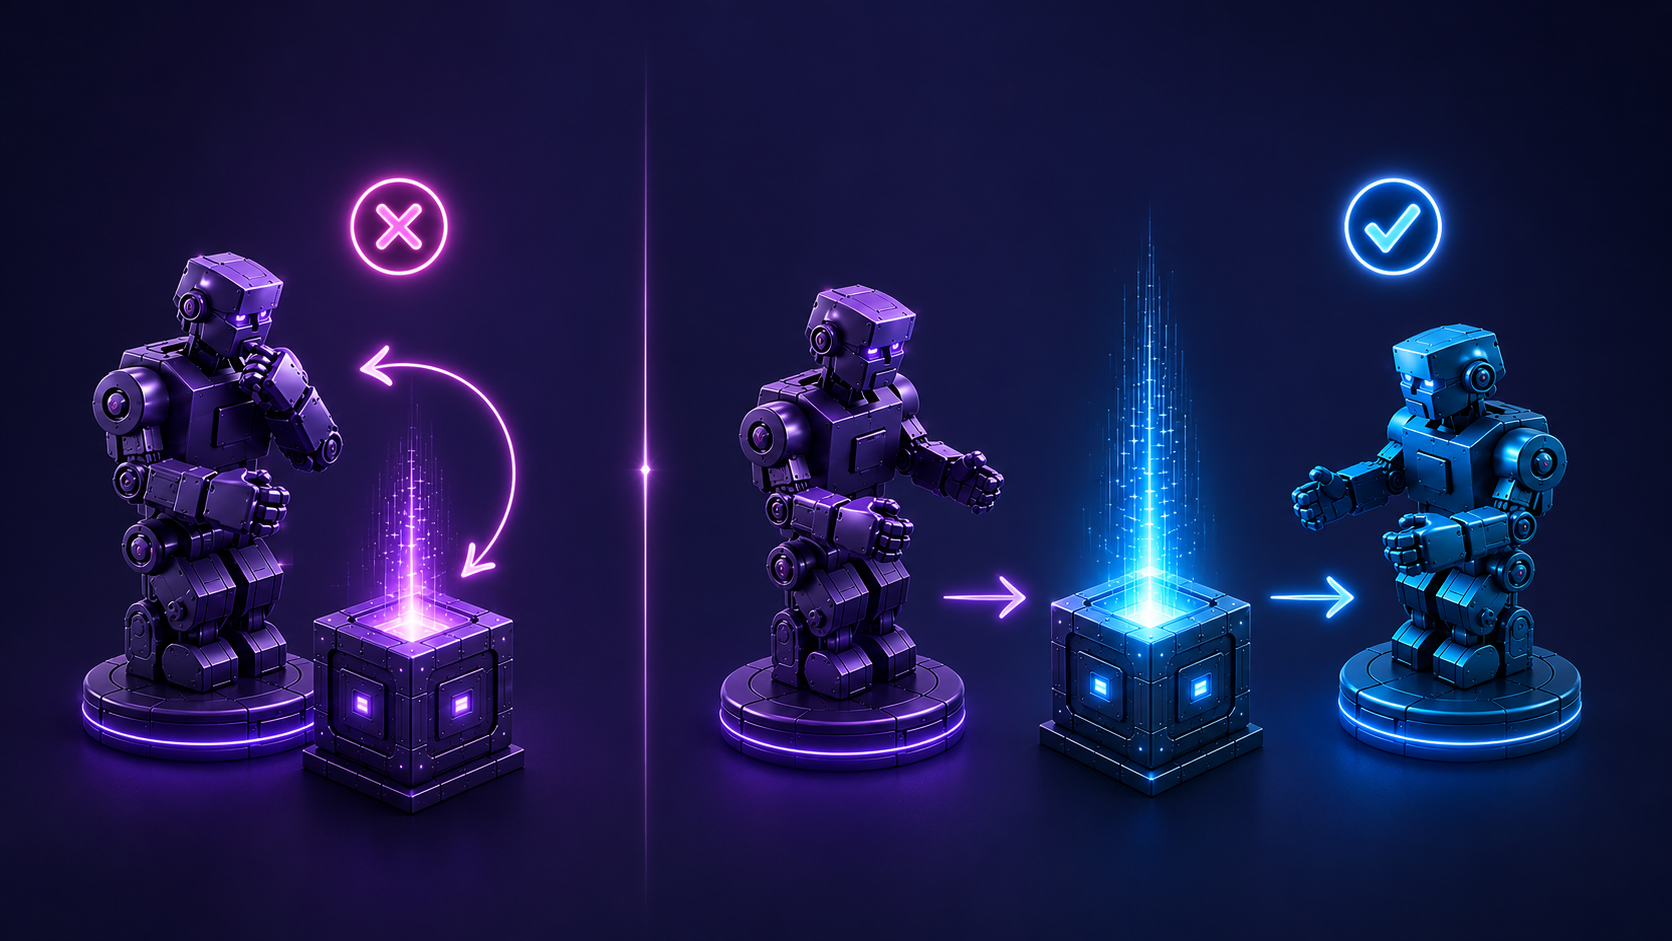
An agent should not grade its own work
AI agents are optimized to complete tasks. That does not make them reliable judges of whether the outcome is correct.
When the same agent creates and verifies the result, it can repeat the same assumptions, overlook the same risks, or shape the verification around its own implementation.
Reliable verification requires independent responsibilities.
Separate execution from verification
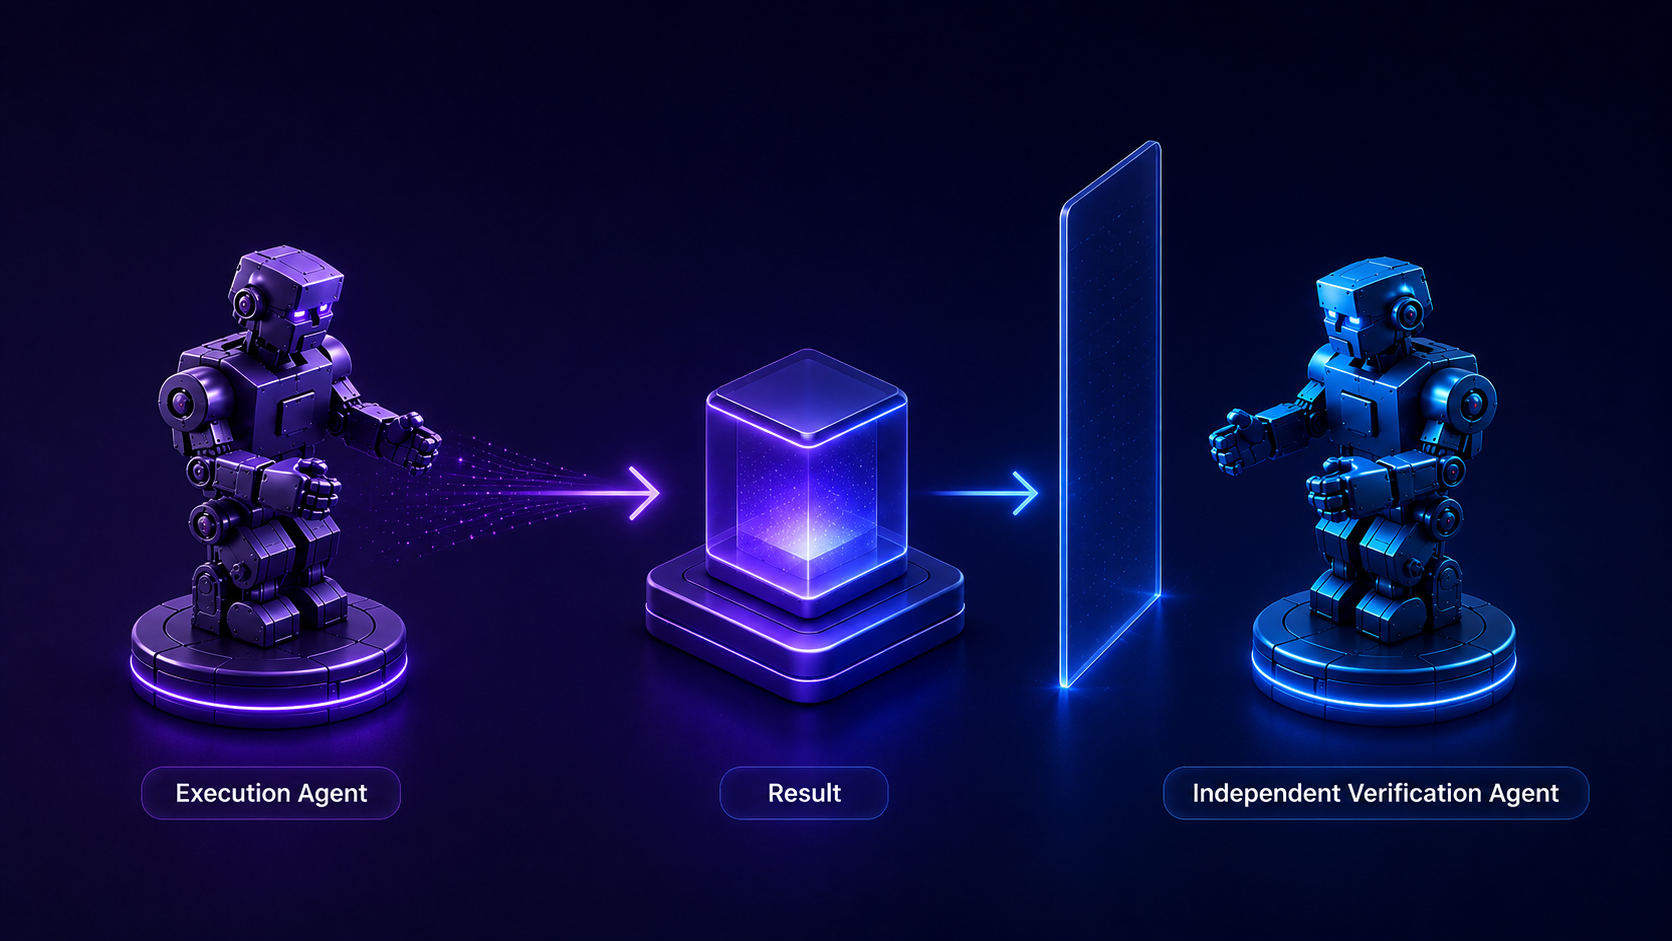
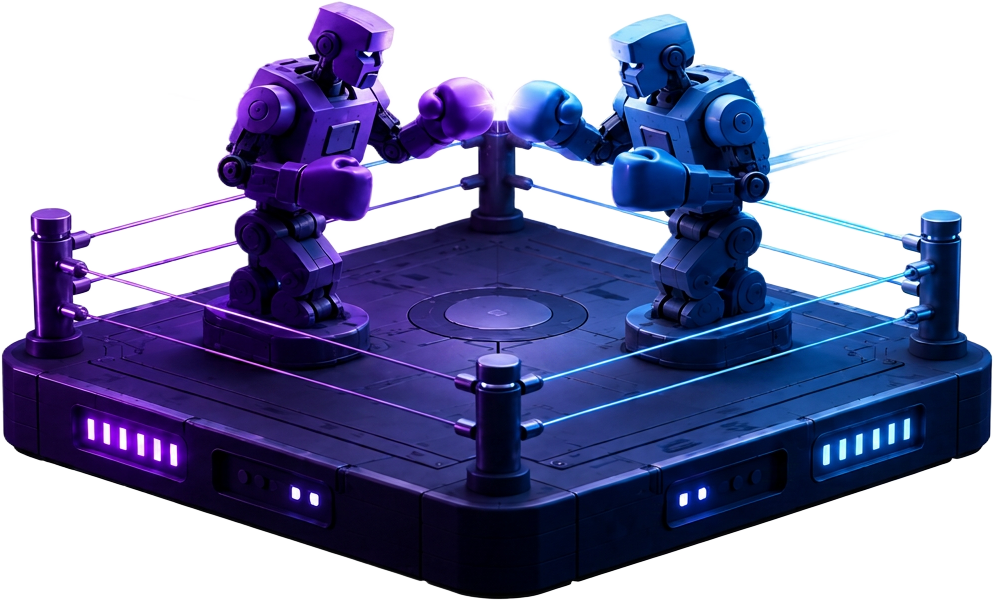
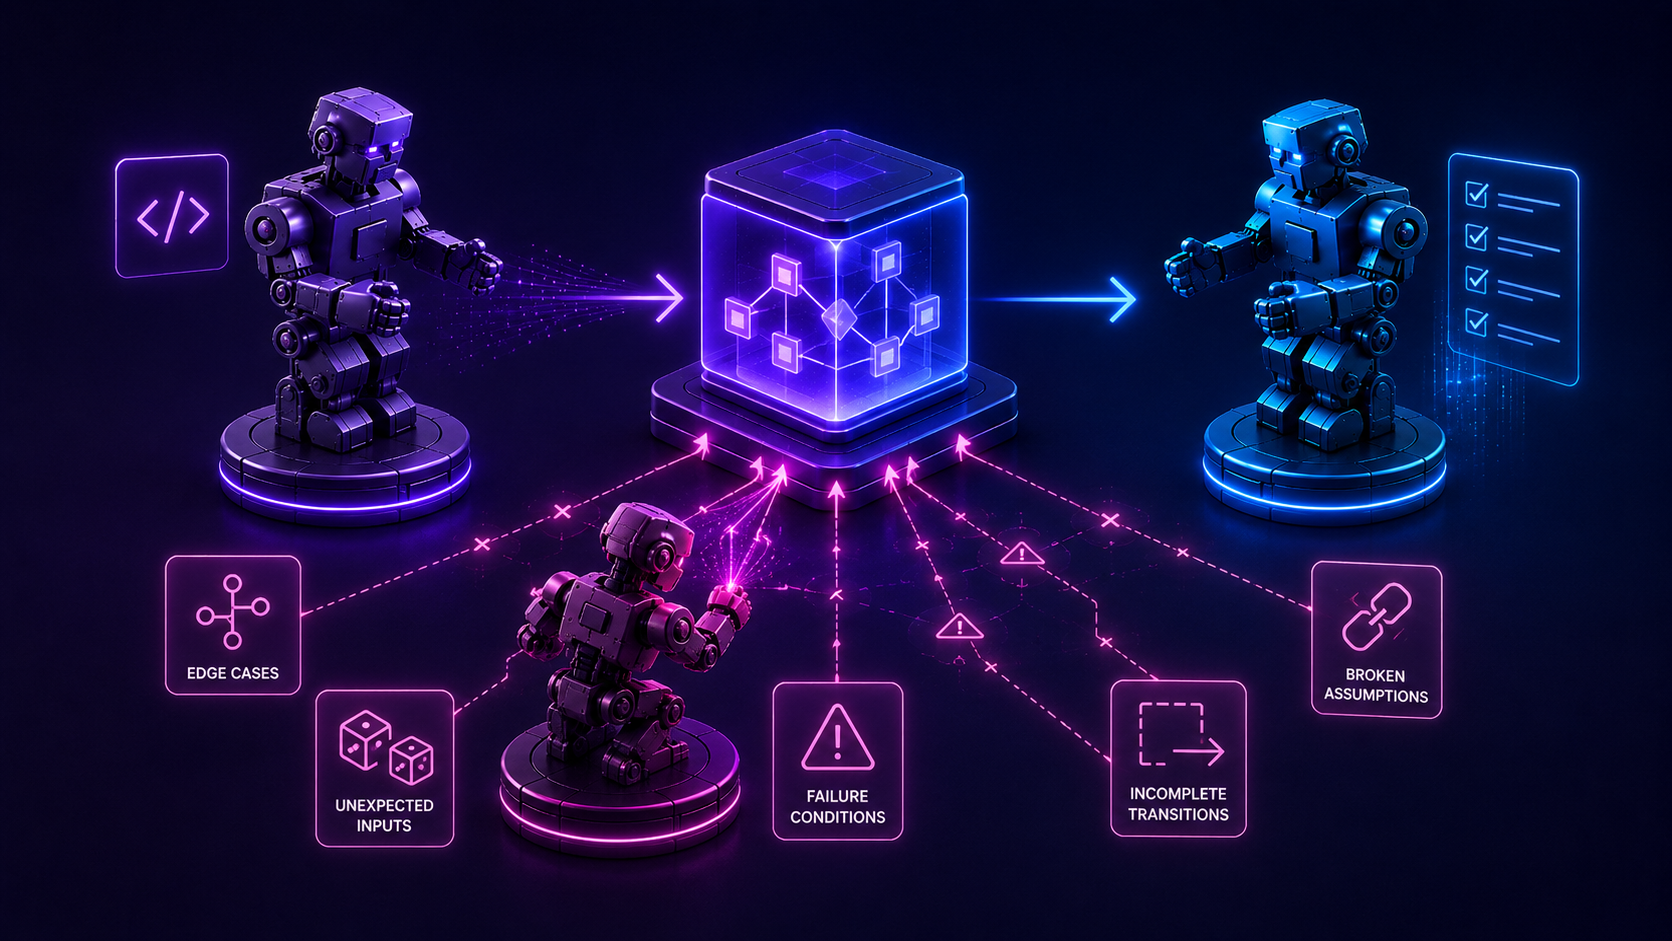
Adversarial verification creates an architectural boundary between the agent doing the work and the agent deciding whether it succeeded.
The execution agent receives the task and produces an outcome. A separate verification agent evaluates that outcome against defined requirements, expected behavior, and observable evidence.
The verification agent must not be able to modify the implementation to make its own job easier.
Independent verification produces a stronger signal than asking an agent to inspect itself.
Add an agent whose job is to break it
A third agent can actively challenge the result instead of only confirming the expected path. It can target:
An automated red-team and blue-team model that can run on every change.
Verification that does not depend on trust
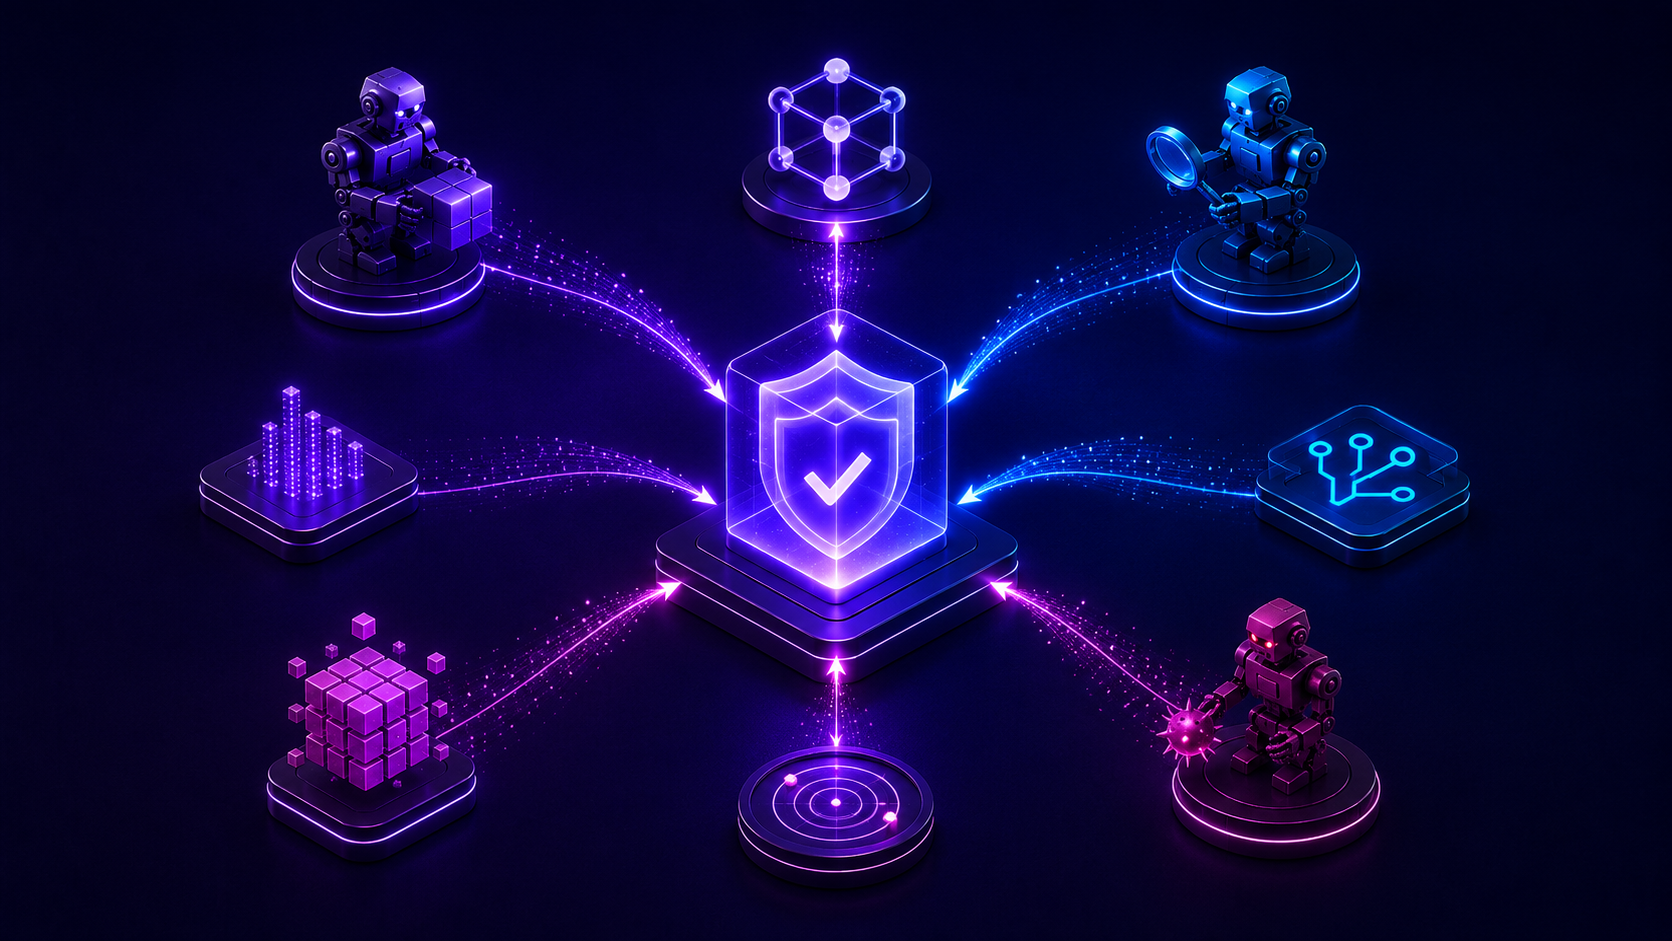
Adversarial verification helps teams move from agent confidence to independent evidence.
Do not ask whether the agent believes it succeeded. Verify that the outcome satisfies the intended requirements.
Make independent verification part of every agent workflow
Agent-generated work needs more than self-assessment. Build systems where execution, verification, and adversarial testing remain separate by design.
See Adversarial Verification in Action